[Summary] Proactive Embedding on Cold Data for Deep Learning Recommendation Model Training
This paper investigates a significant bottleneck in the training of deep learning recommendation models at scale. These models process dense continuous features through multilayer perceptrons and handle categorical features through very large embedding tables. The embedding tables often occupy the majority of the model parameters and memory capacity. In distributed GPU training environments where embeddings are stored in CPU memory and accessed over interconnects, the retrieval of certain embeddings can cause severe delays. The most problematic are cold data embeddings which are rarely accessed items in the table. When the model needs these cold embeddings, the system must perform expensive memory operations that lead to idle GPU cycles and wasted communication bandwidth.
It is observed that this cold data access problem is not adequately addressed by conventional caching or synchronous fetch mechanisms. In practice, cold embeddings are fetched only at the moment they are required which means the GPU may stall while waiting for them (Fig.1 (a)). This waiting time becomes particularly harmful during the inter GPU communication phases where GPUs are already partially idle.
To solve this problem the paper proposes a method called Proactive Embedding (Fig.1 (b)). The central idea is to predict and fetch cold embeddings before they are actually requested in the computation. This proactive retrieval is scheduled to occur during periods when the GPUs are busy with communication so that the embedding fetch latency is hidden behind these existing delays. In effect the approach creates a pipeline in which cold embeddings arrive at the GPU memory just in time for their use in the forward and backward passes of the model.
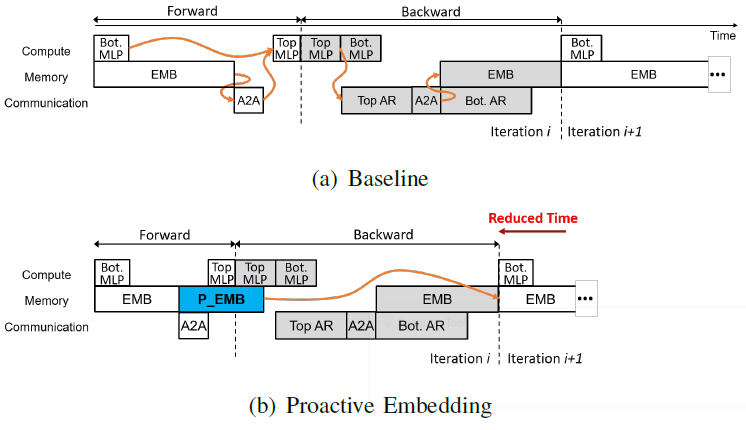
Fig1. Pipeline timeline diagram of DLRM for (a) baseline (reactive embedding) and (b) proposed proactive embedding.
Through experimental evaluation, this paper shows that Proactive Embedding leads to an average improvement of about 46% in training performance. The results also suggest better scalability when the model is trained across multiple GPUs because the technique reduces idle times and increases overlap between communication and computation.
In conclusion, the paper identifies cold data embedding latency as a major challenge in distributed DLRM training and demonstrates that proactive fetching during communication phases can effectively mitigate this issue. The improvement in throughput and scalability confirms the importance of aligning data movement with communication patterns to overcome embedding related bottlenecks in large recommendation workloads.
The Publication : Link